Menu

AI Content Compliance in 2026: Copyright, Labeling, and the EU AI Act.
The intersection of content management and AI now sits at the center of a fast-moving set of ethical and legal questions, and content creators, marketers, and platform owners all need to understand where things stand.
As of August 2026, Article 50 of the EU AI Act requires AI-generated content to be labeled and machine-readable, and platforms including Meta, TikTok, YouTube, LinkedIn, and X each enforce their own separate disclosure rules.
AI-driven LLMs increasingly ingest and repurpose massive amounts of digital content, a number of questions arise.
Key Questions
- How do current copyright laws apply when AI training datasets include third-party content?
- What liabilities do creators face when private or gated work gets scraped without explicit permission?
- What responsibilities do AI developers carry for transparency and respect of intellectual property rights, and how enforceable are opt-out mechanisms like robots.txt or IP restrictions in practice?
At Take3, we’ve been asking these same questions as we bring AI into our own workflow. We’ve spent time researching the answers, working through what the regulations actually require, and figuring out how to use these tools responsibly. This article we share what we’ve learned so far, so you don’t have to start from scratch.
The Reality of Opt-Out Mechanisms and Content Control
Content owners often deploy opt-out tools such as robots.txt files or IP-based restrictions to discourage or block crawlers from accessing their material, but enforcement is often difficult and inconsistent.
Many AI companies claim to respect these exclusions, yet some scrapers ignore them, resulting in unauthorised data harvesting.
A public dispute between iFixit and Anthropic’s ClaudeBot crawler brought these issues to wider attention in 2024, when iFixit’s CEO said the bot had hit the company’s site close to a million times in 24 hours, in what he described as a breach of iFixit’s terms of service.
Anthropic’s crawler was not the only one accused of this kind of aggressive scraping; Freelancer.com and Read the Docs reported similar experiences around the same time.
While this was a public dispute rather than a lawsuit, it fed directly into the copyright litigation that has since followed AI companies more broadly, including a class action filed by The Authors Guild against Anthropic over training data drawn from books.
It’s also worth weighing the trade-off before switching opt-out tools on. Blocking crawlers keeps AI systems out, but it also means your site won’t surface in AI-generated answers, so the same setting that protects your content from being scraped is the one that keeps it invisible to the growing number of people who search through AI tools instead of a traditional search engine.
Implications for Monetised Content
For creators monetising their work, unauthorised inclusion in AI training sets can undercut well-crafted business models.
AI-generated outputs based on proprietary content may compete with or dilute the value of original creations, raising questions about fair compensation or rights management.
This is especially pressing in industries like journalism, where news outlets invest heavily in original reporting but see snippets repurposed without attribution or payment.
The Evolving Copyright Landscape
Copyright law is unable to keep up with the rapid development of AI, and several high-profile lawsuits have been filed against AI companies challenging the legality of scraping copyrighted works without explicit licenses.
The New York Times, along with other major publishers and authors, filed a class-action lawsuit against OpenAI in 2023, alleging unlawful use of their copyrighted content in training datasets, and that case, is setting important precedents about AI training data rights and creator protections.
The Opportunity and the Grey Areas
The opportunity benefits to have your content referenced by LLMs, the core aim of GEO optimisation, is clear, you get amplified visibility, long-tail traffic, and a stronger claim to expertise in your field.
But unlike SEO, where rules are clearly ordered, optimising for LLMs plays out in a legal and ethical frontier that is still being defined.
Some questions must be asked:
- Where does the line between fair use and infringement lie?
- What does it mean for your content to be scraped and reused?
Copyright Considerations
LLMs are typically trained on content that is publicly available, licensed, or in the public domain.
However, many authors may find their content used without clear attribution or consent.
While LLMs don’t store data verbatim, the reuse of patterns and summarised knowledge may still raise questions about ownership and proper licensing.
Licensing Content for AI Use
Using permissive licenses like Creative Commons (for example, CC BY), as shown above, explicitly signals that your content can be reused, referenced, and adapted.
This removes ambiguity and makes it legally easier for AI models to absorb and use your work.
Platform Terms of Service and Data Use
Where you post content matters. Platforms like Medium, Substack, or GitHub may have terms that either permit or restrict how content is scraped and reused, so it pays to read the fine print.
Just because your work is public doesn’t mean it’s legally open-source.
AI Transparency and Consent
A growing demand for AI transparency is reshaping the rules around what data was used to train models and how it was obtained. This affects not only content creators but also the platforms and developers behind LLMs.
The EU’s Official AI Labelling Icons
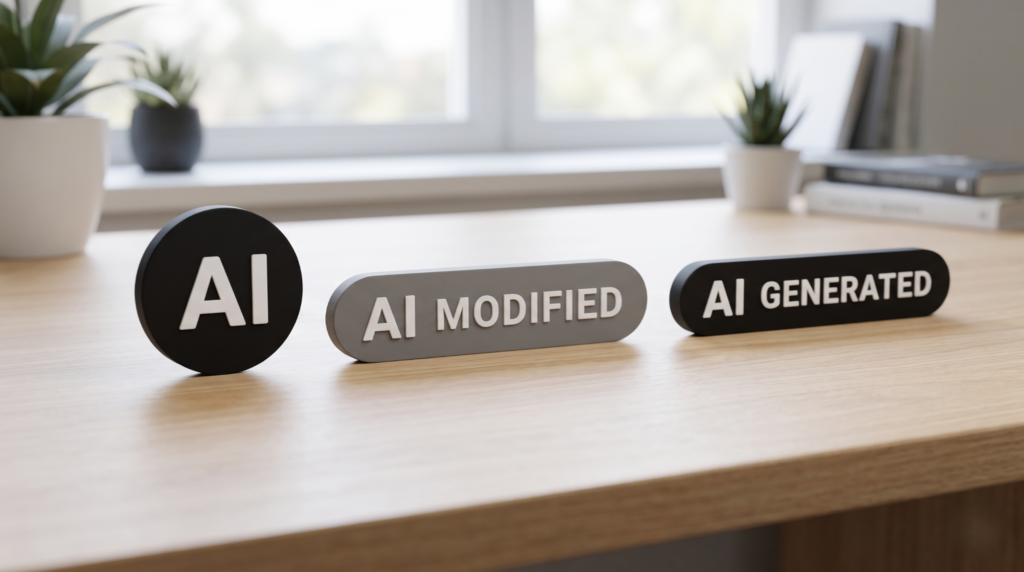
To help brands and creators comply with Article 50, the European Commission has released a standardised set of icons for marking AI-generated and AI-manipulated content. They’re freely available, come in black, white, and two 50 percent transparency variants, and form part of the Code of Practice on marking and labelling of AI-generated content.
Not everything needs one.
The obligation covers two categories specifically: deepfakes, meaning AI-generated or altered image, audio, or video that resembles a real person, object, place, or event closely enough to appear authentic, and AI-generated text published on matters of public interest that hasn’t gone through human review or editorial oversight.
There are three icon variants, each tied to a different level of AI involvement:
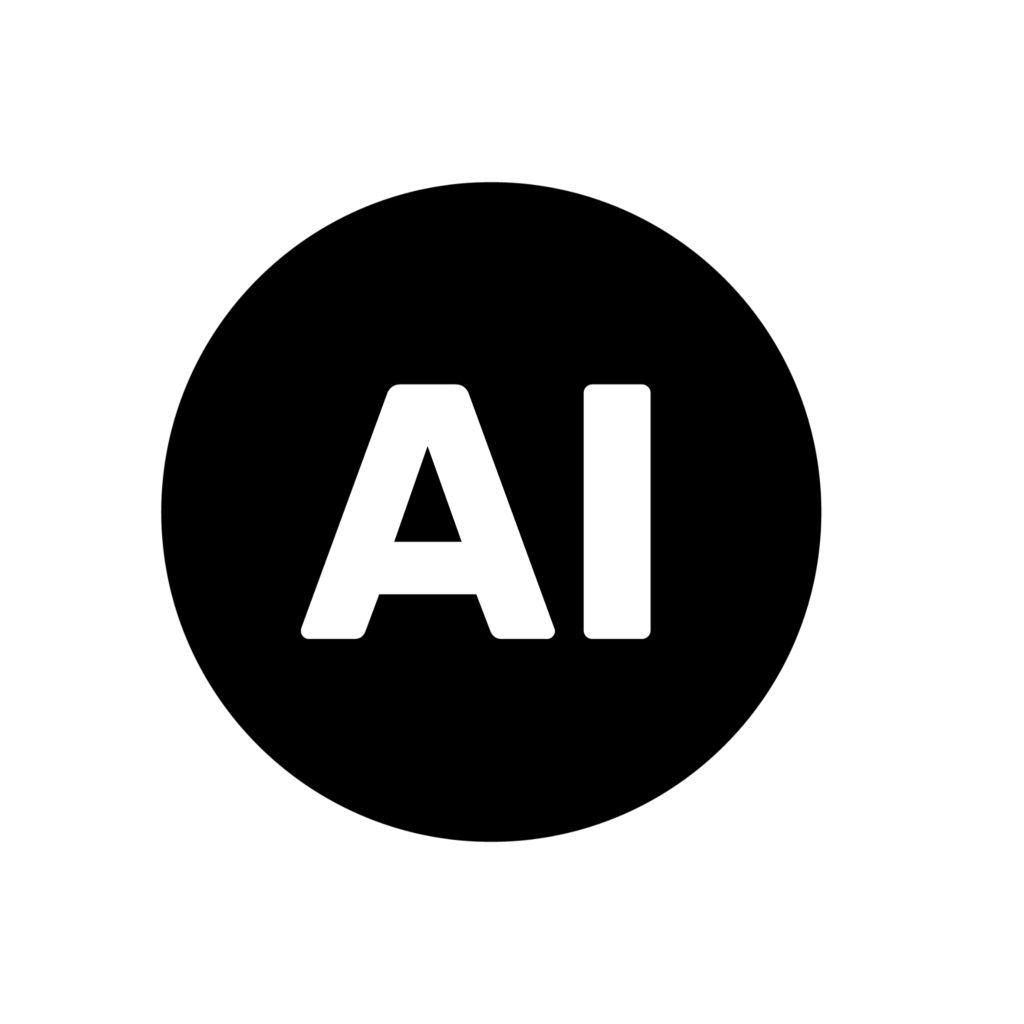
Basic icon. Use for general cases where AI played a role in creating deepfake content or published text, often paired with a custom text label, for example “voices generated with” alongside the icon.
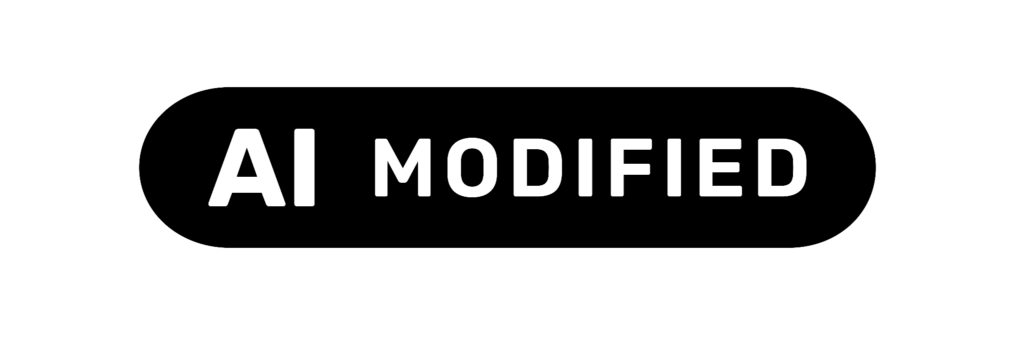
Partially AI-Modified. Use for pre-existing, human-made content that AI has altered into a deepfake or public-interest text, for example a face swapped into a real photograph, or an empty room digitally furnished with AI.
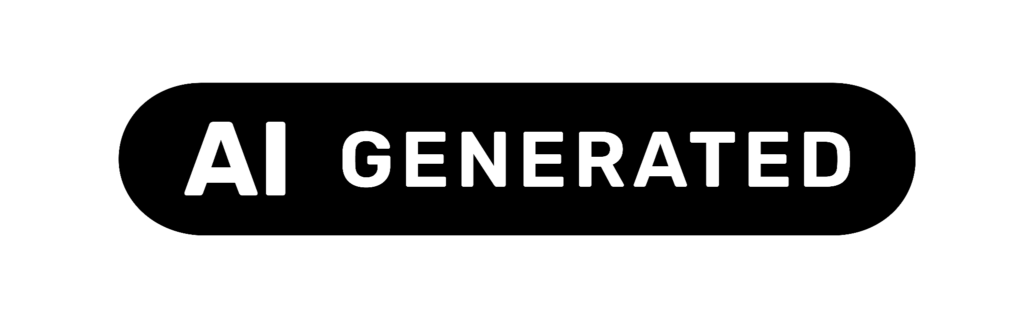
Fully AI-Generated. Use for content with no human-created elements or editorial control beyond the prompt itself, such as AI-composed music, AI-generated news summaries, or synthetic video of a public figure.
There are a number of exceptions which are worth knowing about.
- Content that’s evidently artistic, creative, satirical, or fictional only needs disclosure in a way that doesn’t interrupt the work itself.
- Content authorised by law for detecting or investigating criminal offences is exempt entirely.
- AI-generated text if a person or organisation has reviewed it editorially and taken responsibility for publishing it.
Using the icons is optional, but the Article 50 disclosure obligation isn’t, and adding an icon doesn’t equal compliance on its own.
If you do use them, the Commission’s placement rules matter most: visible on first exposure, unobstructed, embedded in the content itself, and still visible if it’s reshared or downloaded, with plain language and accessibility support alongside.
The icons are free to use without attribution.
Just don’t let their use imply you’ve signed the Code of Practice if you haven’t.
Social Media AI Labeling: A Platform-by-Platform Compliance Guide
Regulation is only half the picture. The platforms themselves have built their own disclosure systems, and these apply globally, regardless of where you or your audience are based. Getting this right matters for compliance and for how your content is treated by each platform’s algorithm.
Meta (Facebook, Instagram, Threads, WhatsApp Channels)
Meta runs two systems. Ads about social issues, elections, or politics that contain photorealistic AI-created or AI-edited media require mandatory self-disclosure.
For everything else, Meta applies a softer “AI info” label automatically when its own generative tools are used or when its detection identifies third-party AI, though Meta itself notes that not all AI-assisted content is caught yet. Meta is also part of a cross-platform provenance coalition with Adobe, Microsoft, and Publicis Groupe, building consistent metadata standards across its apps.
TikTok
TikTok’s rule is broad: any AI-generated content that a reasonable viewer could mistake for real footage must be labelled, using the built-in “AI-generated content” toggle at upload or a visible disclaimer, caption, watermark, or sticker.
TikTok joined the Coalition for Content Provenance and Authenticity (C2PA) Steering Committee in July 2026 as part of its work on Content Credentials.
YouTube
YouTube requires creators to disclose “altered or synthetic” content that looks realistic, through its Creator Studio disclosure tools. Where a creator doesn’t self-disclose, YouTube says it may apply its own label to reduce the risk of viewer harm.
LinkedIn uses the C2PA’s Content Credentials system to label AI-generated content, showing a “cr” watermark that users can click for more detail. Because an AI label on LinkedIn touches professional credibility in a way it doesn’t on more casual platforms, disclosure choices here carry more weight for hiring, client relationships, and reputation than the same choice would on Instagram or X.
X
X has been rolling out AI labelling in stages through 2026, including a “Manipulated Media” tag for deceptive edits and a “Made with AI” toggle creators can apply to synthetic posts, alongside watermarks already applied to content generated by its Grok chatbot.
Enforcement leans heavily on automated detection and the Community Notes system rather than human review, so treat self-disclosure as the safer path regardless of what automated systems catch.
The practical takeaway across all five platforms is the same: label anything a viewer could reasonably mistake for real, keep your metadata clean, and don’t rely on a platform’s detection to catch what you didn’t disclose yourself.
Risks of Misrepresentation, Misinformation, and Brand Dilution
When AI paraphrases your content, it may lose nuance or accuracy. Worse still, your content may end up associated with contexts you don’t endorse, creating brand risk or reputational harm. An ethical content strategy has to account for how AI might repurpose your material, not just whether it gets used at all.
Critical Questions Moving Forward
As the legal and ethical debates evolve, it is important that content creators, managers and industry stakeholders consider several pressing concerns:
- How do we apply existing copyright frameworks when AI systems ingest massive amounts of third-party data?
- What are the liabilities if private content is used without consent?
- What level of transparency and accountability can AI developers maintain when choosing data sources?
- Are current opt-out mechanisms sufficient to protect creator rights, or do we need new legislation?
- How will regulation shape the balance between AI-generated content and human authorship?
While we work through finding the answers to these questions, it is important to stay informed.
The legal frameworks governing AI and content are still being written, and they vary significantly by region, so what’s compliant today in one jurisdiction may not hold in another, and what’s unclear now may be settled within the year.
Keeping up with these developments in your own region, and understanding where your data actually goes once it enters an AI system, is no longer optional due diligence.
It is the baseline for protecting your work and your organisation as this landscape continues to take shape.
Recent Regulatory Proposals and Industry Best Practices
Regulators across the globe are developing AI-specific policies that aim to balance innovation with intellectual property protections.
- The European Union’s Code of Practice on Transparency of AI Generated Content AI Act is now the clearest example in force, and Article 50 transparency and labelling rules enforceable as of August 2026 and its own set of standardised icons for marking AI-generated content.
- The US Copyright Office has been working through clearer licensing frameworks to address AI training datasets, aiming for a balance between fair use and creator rights, though this work is still developing and worth checking against the Office’s current guidance before you rely on it.
- The UK Intellectual Property Office has likewise been consulting on reforms to clarify ownership of AI-generated content and lawful dataset usage.
At the same time, AI developers and content creators continue to adopt best practices to foster compliance and trust, including increasing transparency through data auditing and disclosure of sources, developing opt-in licensing models that compensate creators for dataset inclusion, respecting opt-out signals like robots.txt, and collaborating with creators to build datasets that align commercial and IP interests.
The Role of Open Data Projects
Projects like Common Crawl and LAION aggregate public web data for use in LLM training. Participating in or supporting these initiatives offers a way to make your content accessible while aligning with the open-source and ethical AI communities.
Future Outlook: Ethics-by-Design in Content Strategy
Rather than waiting for the law to catch up, content creators can adopt an ethics-by-design approach:
- Be transparent about licensing
- Design for safe reuse with clear structure and disclaimers
- Monitor AI outputs for misuse or misinterpretation
Ethical visibility is possible. It’s not just about being seen, it’s about being seen right.
Looking Ahead at How We Balance Innovation and Ethical AI Content
We are still in the early stages, but emerging regulations and evolving industry practices are laying the foundation for a future where AI-driven content generation can coexist with strong protections for creator rights. That dual focus on innovation and responsibility is essential. Optimising for LLMs means walking a fine line between opportunity and ethical obligation.
By embracing open licensing, respecting platform terms, and staying informed on global regulation, you don’t just safeguard your work, you help shape the standards of tomorrow. In the age of AI, how your content is used matters just as much as what it says. Make it count.
At Take3, we help creators work through the complex intersection of AI, copyright, and content strategy. If you’re ready to optimise your work for LLM visibility, ethically and sustainably, book a call with us today and let’s future-proof your content the right way.
Information in this article was correct at the time of publishing, please ensure that you regularly check for recent developments in your region as the regulations around AI is evolving at a rapid pace.
AI Transparency Note
The content of this article draws from the author’s own ideas, professional and personal skills and experience, and independent research. Generative AI was used to help with writing, organisation and editing. All of the text was checked and revised by the author, who holds full editorial responsibility for the published piece.
EU AI Act transparency context: European Commission guidance
This article was originally published 10th June 2025 and was updated 11th August 2026 and was updated by Louise Macfarlane, Web3 Strategist at Take3.
More from SEO & GEO
What Marketers Can Learn from Bitcoin’s Trust-Led Growth
Key Takeaways Bitcoin achieved Fortune 500-level brand recognition without a CMO, advertising budget, or commercials. The orange logo remains recognisable even among crypto sceptics and…
A Step by Step Guide on How to Optimise your Content for Inclusion in LLM Public Datasets
In the modern world of web content marketing, one thing is becoming clear. We no longer write just for humans. Today’s most powerful audience…
How to Plan a Successful Token Launch
At Take3, throughout the years we have worked with protocols launching Web3 tokens across DeFi, infrastructure, and consumer Web3. From this real life experience,…
Apply to work with us
Step 1 of 2 — Your Details Almost there Question ${ quizStep } of 7
Tell us about yourself
${ q.hint }
${ q.question }
Is there anything else you'd like us to know?
${ quizCategory }
Your project has potential, but trust signals are thin. Before you scale marketing, you need to build the foundation. That's exactly what we help with.
You've got some trust building blocks in place, but there are gaps that could hold you back. The good news: this is fixable and we know where to focus.
You've built real credibility. The question now is: are you owning the narrative, or letting someone else define it?
We'll be in touch to share what we'd prioritise first.
You've been accepted for a Trust Strategy Call. We'll be in touch to book it.
Sending your results...
${ quizError }